


LLM inference
Serving, quantization, batching, speculative decoding and the cost of every token.
85 links, newest first.
- LLM inferencePost on X
Unsloth Reports Dynamic 1-Bit Quantization of GLM-5.3
An engineer reports quantizing GLM-5.3 to dynamic 1-bit at 217GB, compared with 1.5TB in BF16, and says it retains about 76% top-1% accuracy. They also report running a basic snake game with the quantized model in Unsloth Desktop.
The reported size and accuracy figures are relevant to evaluating low-bit quantization trade-offs.
- LLM inferencePaper
A Year of Production LLM Serving Workloads
The paper analyzes one year of production LLM traffic, reporting workload shifts, short-lived prefix reuse, and tradeoffs between KV-cache locality and load balancing. It says FIFO/LRU can match or outperform more complex cache policies.
The findings can inform cache-policy and load-balancing choices in LLM serving systems.
- LLM inferenceArticle
dstack introduces Presets for portable inference optimization
dstack presents Presets, an open-source toolkit that uses agents to streamline inference optimization and provides a portable format for optimization results.
Engineers can explore an approach to carrying inference optimizations across deployment environments.
- LLM inferenceArticle
Claude inference hooks gate prompts before inference
Claude inference hooks send each governed prompt to an organization's AI security server for an allow-or-deny verdict before inference proceeds.
Engineers can use the hooks to apply security checks before prompts reach inference.
- LLM inferenceArticle
Reference for MSLK kernels and APIs
A searchable reference for MSLK covering attention, GEMM, quantization, MoE, convolution, FlyDSL, and developer utilities. The author says the project is undocumented and that the reference was created with agents.
It can help engineers explore MSLK kernel APIs and capabilities.
- LLM inferenceRepository
PR adds DeepSeek V4 Flash 0731 support on two DGX Sparks
The pull request updates the default checkpoint to DeepSeek-V4-Flash-0731 and installs the checkpoint-owned encoder on both ranks.
Useful to engineers evaluating a two-DGX-Spark setup for DeepSeek V4 Flash inference.
- LLM inferenceRepository
GLM-5.2 EXL3 serving profile for four RTX PRO 6000s
A GitHub repository provides a reproducible GLM-5.2 EXL3 MTP3 serving setup and thermal profile for four RTX PRO 6000 Blackwell GPUs.
It may help engineers reproduce a specific multi-GPU inference setup and its thermal profile.
- LLM inferenceRepository
A registry of silent LLM serving-path failures
The GitHub repository catalogs LLM serving issues such as mismatched reasoning fields, tool calls rendered as text, quantization labels that do not match active kernels, and misleading health checks. Entries describe symptoms, mechanisms, checks, and fixes.
It can help engineers diagnose serving configurations that appear healthy but produce incorrect outputs.
- LLM inferenceRepository
KTransformers targets heterogeneous LLM inference and fine-tuning
KTransformers is an open-source framework for heterogeneous LLM inference and fine-tuning optimizations. The post claims it can run DeepSeek-V3 and R1 with 139K context in 24GB of VRAM by placing some experts on the CPU.
Its GPU/CPU placement approach may help engineers explore LLM inference on hardware with limited VRAM.
- LLM inferencePaper
StreamDQ dequantizes LLM weights in the HBM base die
The paper presents StreamDQ, a near-memory dequantization architecture for high-throughput LLM inference. It performs on-the-fly dequantization in the HBM base die while preserving conventional GPU load semantics.
Engineers evaluating LLM inference architectures can assess an approach that moves dequantization near memory.
- LLM inferenceRepository
Colibri streams MoE experts from disk in a pure C inference engine
Colibri is a zero-dependency C engine for running MoE models, streaming experts from disk on demand. The post says it runs GLM-5.2 (744B parameters) on a laptop with 25GB RAM.
On-demand expert streaming offers an approach to running large MoE models with limited memory.
- LLM inferencePaper
KV Cache Quantization: More Bits for Keys Than Values
The ACL 2026 paper examines KV cache compression. The post says 4-bit keys with 2-bit values can work well, while reversing those bit widths severely degrades accuracy.
Engineers tuning KV cache memory use can assess how quantization choices affect model accuracy.
- LLM inferenceRepository
Ridgeline: a roofline profiler for LLM inference
Ridgeline is a small roofline profiler for LLM inference, built with PyTorch.
It may help engineers profile LLM inference workloads using a roofline model.
- LLM inferencePaper
JetSpec uses parallel tree drafting for speculative decoding
JetSpec uses a single forward pass with causal conditioning to build coherent draft trees for speculative decoding. The post reports speedups of up to 9.64× on MATH-500 and 4.58× on open-ended chat.
The paper explores how parallel draft-tree construction can improve speculative decoding speed.
- LLM inferenceRepository
TinyRouter learns to route questions among open models
TinyRouter is a roughly 10K-parameter router that selects an open model and its role for each question. The author reports beating each individual model on MMLU, matching the best model on math, and says further experiments are needed.
Engineers can examine how model diversity affects routing and its measured gains.
- LLM inferenceArticle
How speculative decoding verifies draft tokens
Speculative decoding uses a fast, small draft model to propose several tokens, which a larger target model verifies in parallel. The post says this can generate multiple tokens per step without sacrificing output quality.
Engineers can understand how draft-and-verify inference may speed up token generation.
- LLM inferencePost on X
DS4 Fork Adds Multi-Machine Tensor-Parallel Inference
The post describes a fork of antirez/ds4, a native inference engine for DeepSeek V4 Flash/PRO. It adds support for combining `--tensor-parallel` with `--role` for multi-machine, multi-GPU inference.
Engineers evaluating distributed DeepSeek V4 inference can assess whether this fork supports their deployment setup.
- LLM inferenceRepository
Gradbot runs parallel models for faster voice-agent responses
A community contribution to Gradbot runs MiniMax-M2-her to stream a short acknowledgement to TTS while MiniMax-M2.7 reasons and makes tool calls in the background.
Parallel generation can reduce silence while a voice agent handles reasoning and tool calls.
- LLM inferenceArticle
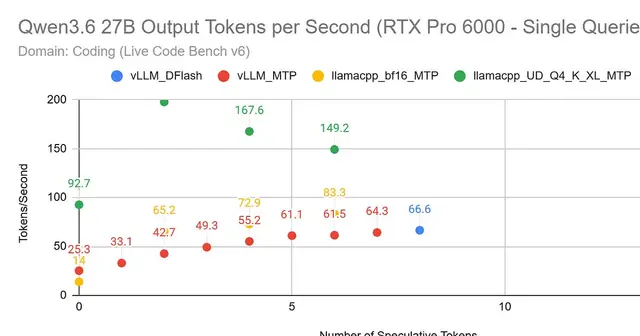
DFlash vs. MTP speculative decoding benchmarks on Qwen3.6
The article benchmarks DFlash and MTP with vLLM and llama.cpp across math, coding, and chat workloads. DFlash reaches up to 4× speedup on Qwen3.6 27B, while MTP often performs better on Qwen3.6 35B A3B.
The results show that speculative decoding performance depends on the model and workload, helping engineers choose what to benchmark.
- LLM inferenceArticle
TokenSpeed inference engine for agentic workloads
TokenSpeed is an LLM inference engine designed for agentic workloads. Its described features include compiler-backed parallelism modeling, a high-performance scheduler, restricted KV resource reuse, and a pluggable kernel system for heterogeneous accelerators.
Its scheduler, parallelism, and KV resource management are relevant to engineers optimizing inference for agentic workloads.
 arxiv.org
Build with AgentLog
Send your own newsletter
CommsHarbor keeps contacts, consent and one-click unsubscribe together.
Free workspace
Open CommsHarbor