


Reinforcement learning
- Reinforcement learningArticle
Post claims OPD is more efficient than RL
The author claims OPD uses compute and samples more efficiently than RL, which they say finds high-reward reasoning traces. The linked PDF is titled “llm_distillation.pdf.”
The claim concerns the compute and sample efficiency of approaches to training language models.
- 4 months ago @JongwonPar9958
A proposed test for reward-hacking mitigations
The post contrasts blocking suspicious tool calls and returning dummy information with penalizing a CoT monitor, which it says can lead to obfuscation. It asks whether a head-to-head test in the same environment has measured this difference.
The comparison could help engineers evaluate whether interventions stop reward hacking or merely make it harder to detect.
- 6 months ago @cwolferesearch
Why RL Scaling Laws Differ from Pretraining
The post contrasts pretraining and RL scaling laws, noting that RL compute includes sampling and policy updates and may be measured in FLOPs or GPU hours. It also distinguishes within-run and across-run extrapolation.
It highlights compute and evaluation choices that complicate comparisons and extrapolation in RL experiments.
- Reinforcement learningArticle
Overview of RL methods for reasoning LLMs
A blog post surveys RL methods including REINFORCE, PPO, RLHF, GRPO, RLOO, Dr. GRPO, DAPO, CISPO, MaxRL, DPPO, and ScaleRL.
Useful as a single starting point for engineers comparing RL methods used with language models.
- Reinforcement learningArticle
Running verl RLHF Training on AMD GPUs with ROCm 7.0
An AMD ROCm blog describes deploying verl for RLHF training on AMD GPUs, with ROCm optimization and Docker scripts. It reports throughput and convergence results.
Useful for engineers evaluating AMD GPU infrastructure and deployment options for verl-based RLHF.
CogRouter adapts reasoning depth at each agent step
CogRouter uses four hierarchical cognitive levels to adjust reasoning depth for LLM agents. Its training combines supervised fine-tuning and policy optimization; the post reports an 82.3% benchmark success rate for a 7B model.
Step-level reasoning control may help engineers trade off agent performance and token use.
Self-distillation for continual learning without reward functions
The post describes a method that uses a model conditioned on a demonstration as a teacher for the same model generating text without that demonstration. The student is trained to match the teacher’s token distributions on its generated text.
This approach may help engineers train models on new tasks while reducing catastrophic forgetting, without defining a reward function.
- Reinforcement learningArticle
Online RL for HPC Code Generation with Machine Benchmarks
The article describes using online reinforcement learning with real-machine benchmark rewards to improve LLMs’ HPC code generation. It notes that generated code’s runtime performance is not guaranteed.
Engineers can see an approach to training code-generation models using measured runtime performance.
- 9 months ago @askalphaxiv
MaxRL uses likelihood-based training for binary-reward RL
The post describes MaxRL, which uses additional rollouts to approximate maximum-likelihood training with non-differentiable sampling. It says the method addresses underweighting of hard prompts and reports up to 20× test-time efficiency versus GRPO.
The approach may matter to engineers evaluating reward optimization and compute scaling for RL systems.
- Reinforcement learningArticle
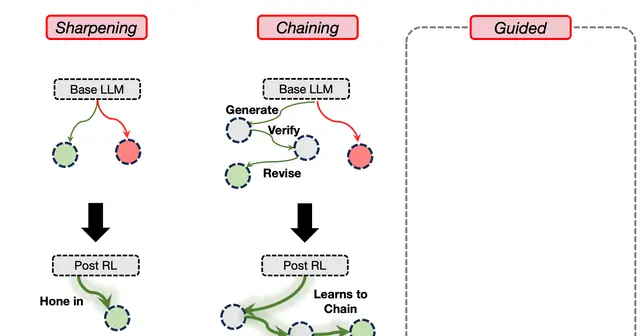
Exploration regimes for scaling LLM reinforcement learning
A CMU blog post describes three LLM RL exploration regimes: sharpening, chaining, and guided exploration. It says standard RL uses the first two and can plateau on hard problems, while mixing easy and hard data can cause interference.
The exploration and data-mixing challenges described can inform how engineers design RL training for difficult tasks.
- 9 months ago @0xSero
A 14B Coding Model Fine-Tuned with SFT and DPO
The article describes fine-tuning a 14B model on coding conversations using an SFT and DPO pipeline, and reports numbers, costs, and frustrations.
It offers a concrete account of personal-data fine-tuning and the costs and results engineers may need to evaluate.
- Reinforcement learningProject
slime v0.2.2 adds Int4-QAT and R3 support
The slime v0.2.2 release lists memory and performance improvements, Int4-QAT training, and full R3 support with DeepEP and MTP. It also upgrades to SGLang v0.5.7 and the Megatron dev branch.
Engineers using slime can review new training capabilities, rollout support, and performance changes.
- 9 months ago @MichaelElabd
Architecture choices affect continual learning and forgetting
The post describes a paper comparing architectures for continual learning. It says wider networks and removing or reducing global average pooling can improve retention, while ResNets and WideResNets learn new tasks quickly but forget more.
Architecture choices can influence the stability–plasticity trade-off, not just the continual-learning algorithm.
Self-Aligned Reward for LLM Reinforcement Learning
Self-Aligned Reward (SAR) is presented as a reward signal for LLM reinforcement-learning pipelines, compatible with PPO and GRPO. The post says it aims to improve reasoning quality while reducing token length.
Engineers can evaluate SAR as a reward module for balancing reasoning quality and generation length.
- Reinforcement learningArticle
Unsloth documents long-context GRPO training
Unsloth’s documentation describes long-context reinforcement learning fine-tuning with GRPO. The post claims its batching algorithms enable 380K context for gpt-oss on a 192GB GPU.
Useful for engineers exploring long-context RL fine-tuning and its stated hardware requirements.
- 10 months ago @twni2016
Bayesian Generalization for Offline Model-Based RL
The post describes a paper that explores dropping conservative constraints in offline RL and relying on Bayesian principles for adaptive generalization. It reports that long-horizon rollouts make this approach work.
It highlights an alternative to conservative offline RL that engineers can evaluate for model-based learning.
- 10 months ago @EpochAIResearch
Interviews on the RL environment ecosystem
Chris Barber and JS Denain interviewed 18 people from RL environment startups, neolabs, and frontier labs about a field the post says mostly stays behind closed doors.
The interviews offer engineers a view into how RL environments are being developed across organizations.
Comparing SFT and reinforcement fine-tuning for continual post-training
The paper compares supervised fine-tuning and reinforcement fine-tuning for continual post-training of foundation models. Its title states that reinforcement fine-tuning naturally mitigates forgetting.
The comparison may help engineers choose post-training approaches when adapting models to evolving tasks.
Full-stack fine-tuning for the Q programming language
The technical report presents an open-source approach for adapting language models to Q, a programming language used in quantitative finance. It addresses the challenge of applying LLMs to niche languages under-represented in training data.
The report may offer engineers a practical approach to adapting LLMs for specialized programming languages.
- 10 months ago @guohao_li
SETA Releases RL Environments for Terminal Agents
SETA says it released 400 terminal-agent training environments, an RL training pipeline, and weights for SETA-RL-Qwen3-8B. It also describes its CAMEL terminal toolkit harness as state of the art on terminal-bench.
The release could provide engineers with environments, a training pipeline, and model weights for terminal-agent RL experiments.
 arxiv.org
 hgpu.org
 unsloth.ai